Back to Catalog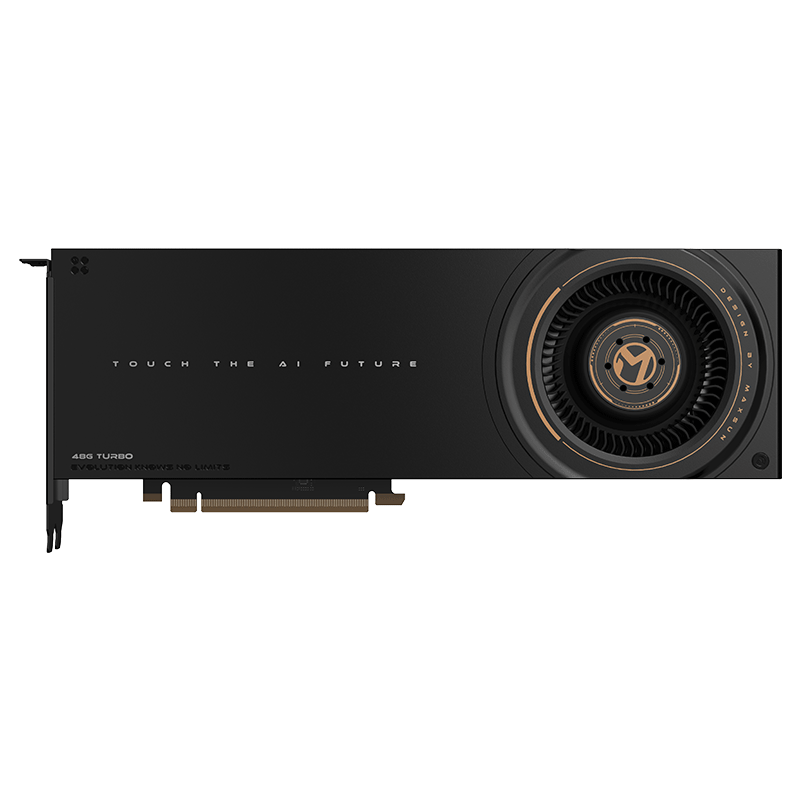
 View
 View
MAXSUN Intel Arc PRO B60 Dual 48G Turbo Graphics Card AI Computing Accelerator for Model Inference and Deep Learning Local Deployment Support for Lobster Farming
CN¥12,999.00
SKU: 100306655304
Status:In Stock (6)
ID: 100316295372
Weight: 1515.00 g
Dims:404x218x85 mm
Specifications
- Graphics card model
- Pro B60
- Chipset
- Intel
- Port Type
- PCIe 5.0
Variants / Sale Attributes
Model: [Double Core] 48G
Package Contents
Graphics card *1
Product Description
Overview
- Brand
- MAXSUN
- Product Series
- MAXSUN Intel Arc Pro B60 Dual 48 G Turbo Graphics Card
Dual GPU design with 48GB GDDR6 large video memory
PCIe 5.0 x8 + PCIe 5.0 x8 interface for high bandwidth and powerful computing performance
Additional details
- Triple cooling system
- turbo fan cooling, large vapor chamber heat spreader, and metal backplate for efficient heat dissipation
Dual-slot width design suitable for multi-GPU synchronous computing environments
Optimized software ecosystem with native support for PyTorch, ISV support, IPEX-LLM inference engine, and compatibility with vLLM
Supports Intel LLM-Scaler for large language model (LLM) acceleration
Compatible with various LLM models including FP8, INT4 precision and models such as DeepSeek-R1 series, Qwen3 series, LLMMOE, multi-modal and embedding models
Supports up to 16-card interconnection (Battlematrix) with total memory up to 384GB for smooth operation of 100B+ parameter models
Similar Products
In Stock
graphics card
Panlei (PELADN) Kaitian R5 230 2G D3 Desktop Computer for Home Office Entertainment, High-Definition Multi-Screen PC with Dedicated Graphics Card
R5 230-2G Heat Sink
CN¥179.00
In Stock
graphics card
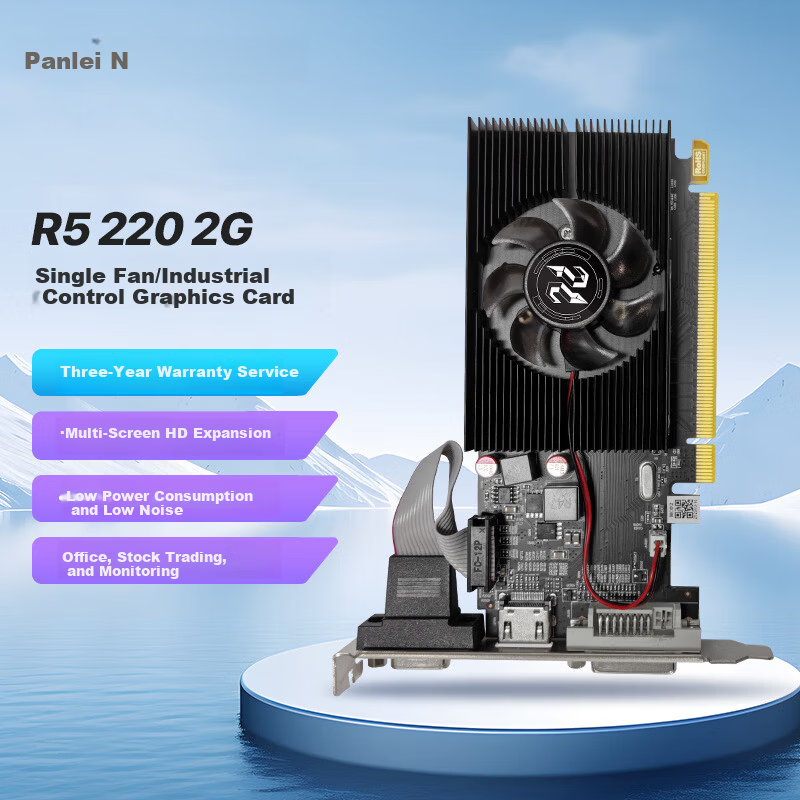
PELADN Kaitan R5 220 2G DDR3 Fan Edition Dedicated Graphics Card for Home Office Multi-Screen Stock Trading PC
[R5 2202G] with fan model
CN¥169.00